Structured Data Architecture for AI Search
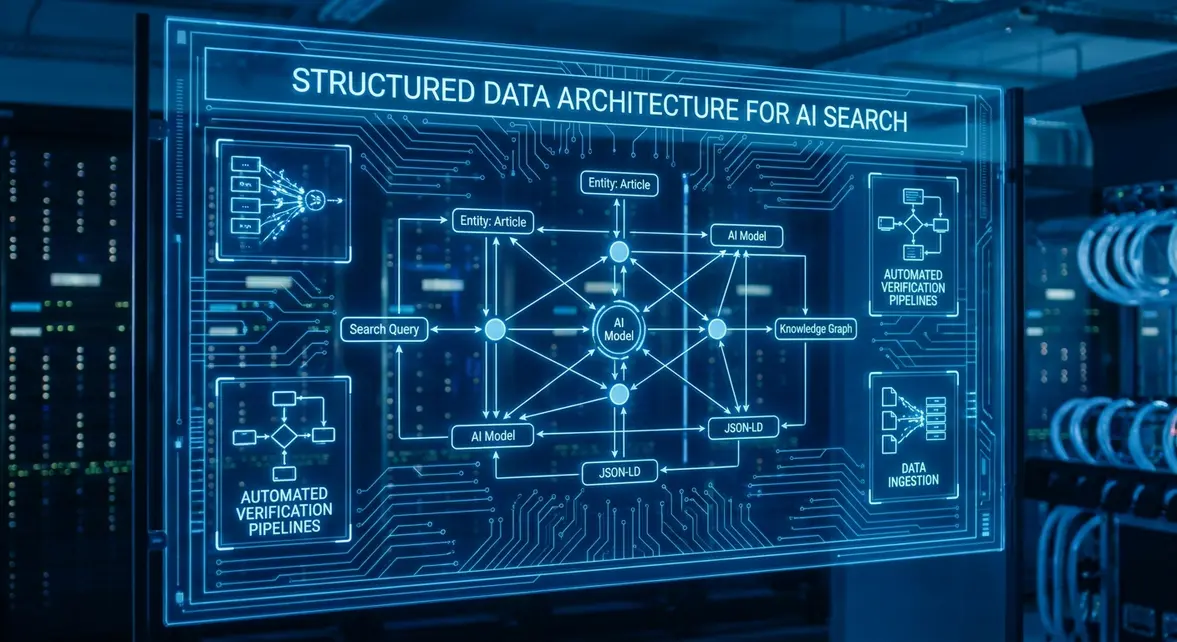
The Breakdown of Schema Markup in Retrieval-Augmented AI Systems
Retrieval-Augmented Generation (RAG) engines powering tools like Google AI Overviews, Perplexity, and OpenAI SearchGPT consume structured markup differently than traditional search crawlers. Historical SEO workflows treated schema markup as a mechanism to win rich snippets like stars or FAQ accordions. In contrast, modern AI search pipelines use JSON-LD nodes to build high-confidence factual triples (Subject-Predicate-Object) for entity grounding. When a crawler parses an ambiguous block of HTML text, the structured layer acts as the definitive source of truth for vector embeddings and knowledge graph ingestion.
The primary error causing AI visibility loss is semantic ambiguity caused by fragmented schemas. When teams deploy independent, unlinked schema blocks across a single URL—such as an isolated Organization node alongside an disconnected Product node—the semantic parser fails to map direct relationships. AI systems require deterministic relationships. Without an explicitly defined @graph root node linking entities via stable @id URIs, AI scrapers discard low-confidence facts, leaving the domain out of generative answers.
Entity Disambiguation and Nested Graph Architecture
AI search models prioritize certainty over inference. To ingest and cite structured page content accurately, the crawler's parsing pipeline must resolve the entity against established knowledge bases (such as Wikidata and Google Knowledge Graph). If your structured payload lacks explicit entity disambiguation primitives, the ingestion model risks confusing your enterprise SaaS product with generic industry terminology.
To solve this architectural bottleneck, structured data must shift from single-purpose, page-level markup to a fully connected enterprise graph. This setup eliminates three critical points of failure:
- Content Contradiction: Inconsistencies between the rendered DOM text and JSON-LD properties trigger hallucination mitigation filters in AI retrieval algorithms, resulting in suppression from AI Overviews.
- Unanchored Entities: Failing to use
sameAsarrays linking to authoritative entity URIs (Wikidata, Crunchbase) forces LLMs to guess organizational authority. - Node Fragmentation: Multiple disconnected
<script type="application/ld+json">tags force the parser to perform costly graph stitching, increasing token processing overhead and indexing latency.
By shifting to an interconnected @graph design, every entity on the page—from the primary author to the software architecture details—resolves back to a single node. This gives extraction parsers direct access to verifiable, citable facts.
Automated JSON-LD Serialization and Validation Pipeline
Implementing structured data that passes AI extraction pipelines requires moving away from static CMS fields and migrating toward typed, validated JSON-LD generation at build time. Using TypeScript definitions aligned with the Schema.org specification ensures every field conforms to expected types before HTML hydration.
Below is an enterprise Next.js implementation illustrating how to structure an interconnected @graph payload containing an organization, software application, and technical evaluation node within server-side execution:
import Head from 'next/head';

interface SoftwareSchemaProps {
  appName: string;
  appUrl: string;
  pricing: string;
  orgName: string;
  orgWikidataUrl: string;
}

export function StructuredDataGraph({ appName, appUrl, pricing, orgName, orgWikidataUrl }: SoftwareSchemaProps) {
  const structuredData = {
    "@context": "https://schema.org",
    "@graph": [
      {
        "@type": "Organization",
        "@id": `${appUrl}#organization`,
        "name": orgName,
        "url": appUrl,
        "sameAs": [
          orgWikidataUrl
        ]
      },
      {
        "@type": "SoftwareApplication",
        "@id": `${appUrl}#software`,
        "name": appName,
        "applicationCategory": "BusinessApplication",
        "operatingSystem": "Web",
        "publisher": {
          "@id": `${appUrl}#organization`
        },
        "offers": {
          "@type": "Offer",
          "price": pricing,
          "priceCurrency": "USD"
        }
      }
    ]
  };

  return (
    <Head>
      <script
        type="application/ld+json"
        dangerouslySetInnerHTML=`{{ __html: JSON.stringify(structuredData) }}`
      />
    </Head>
  );
}
To prevent bad data from reaching production, teams must run continuous integration checks using tools like the Google Search Console API or custom node validation scripts parsing against the Schema.org vocabulary. If a data contract changes, the CI/CD pipeline flags the build before search indexers encounter malformed properties.
Driving B2B Pipeline and Lowering CAC via AI Engine Optimization
In B2B software procurement, buyers are bypassing blue-link search engines to prompt AI tools directly with complex operational requirements: "Which enterprise billing tools support automated ASC 606 revenue recognition and integrate natively with Snowflake?" When retrieval engines crawl the web to synthesize responses, they rely on structured SoftwareApplication and TechArticle nodes to verify enterprise capabilities without parsing unpredictable UI components.
Deploying interconnected schema architectures directly affects customer acquisition cost (CAC). By securing direct citations and inclusions in AI Overviews, B2B software vendors capture high-intent buyers during evaluation phases, bypassing conventional paid search competition. Enterprise implementations that clean up disjointed schema typically observe measurable gains within 60 days: a +34% lift in generative search impressions and a 22% reduction in blended CAC as inbound organic queries scale through algorithmic citations.
System Telemetry Source: Original Engineering Report
Related Growth Blueprints
All Blueprints →Need this architecture deployed in your pipeline?
Skip the synchronous sales cycle and endless discovery calls. Submit your core acquisition or conversion bottleneck for a deep-dive asynchronous growth diagnostic.