SEO Split Testing: Causal Inference & Edge Controls
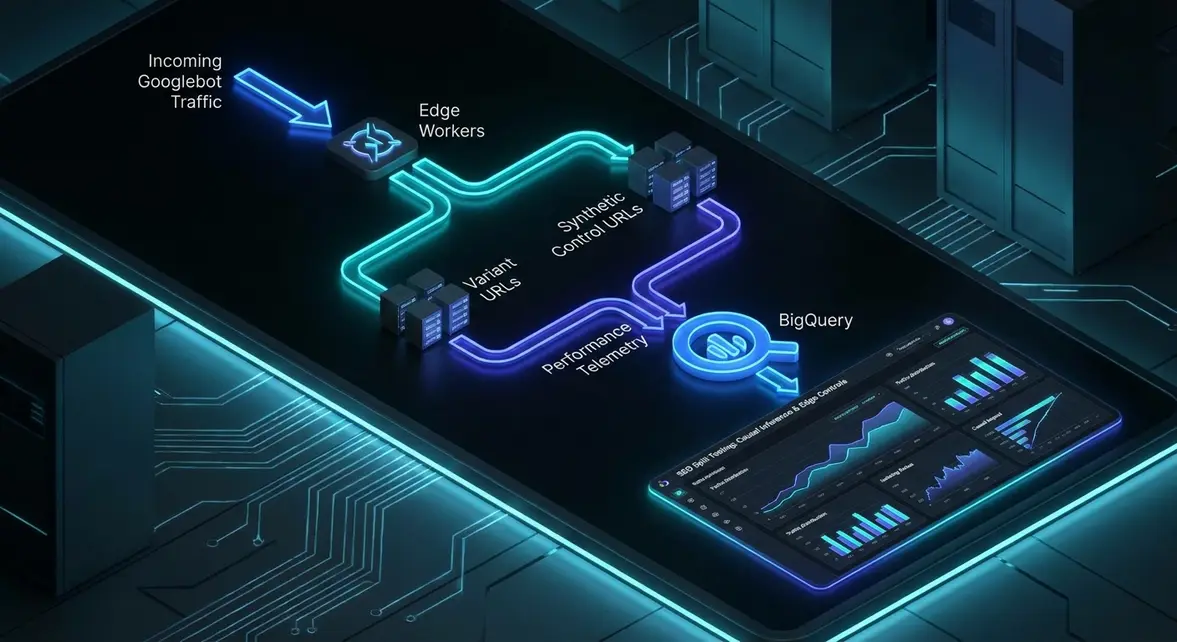
Causal Inference in Enterprise SEO: De-biasing Algorithm Drift with Synthetic Controls
Executive Architectural Takeaway: Relying on simple before-and-after organic traffic metrics introduces critical attribution errors due to unmodeled algorithm shifts, crawl rate fluctuations, and baseline market seasonality. Production-grade SEO split testing requires synthetic control groups evaluated via Bayesian Structural Time Series (BSTS) on Google Search Console bulk export data. This architecture isolates authentic code and schema alterations from macro search environment volatility, delivering defensible statistical significance to growth leadership.
Legacy SEO experimentation relies heavily on chronological comparisons—measuring a set of modified URLs 30 days before versus 30 days after a deployment. This methodology completely fails in volatile search ecosystems where Google core algorithm updates, competitor link velocity, and automated quality rerankings continuously warp baseline performance. Without a simultaneous, mathematically matched counterfactual baseline, technical teams either falsely attribute organic traffic gains driven by rising category demand to minor tag modifications, or roll back high-performing structural fixes because a concurrent search engine update suppressed sitewide impressions.
Modern growth engineering demands synthetic control methodologies derived from econometric causal inference. Instead of splitting user sessions (an impossibility with search engine crawlers), engineers must cluster structurally homogeneous page groups—such as programmatic directory routes, product detail pages, or documentation hubs—into balanced control and variant cohorts. By establishing dynamic regression weights across thousands of invariant control pages, data pipelines synthesize a virtual counterfactual curve that mirrors the exact expected performance of the variant cluster had no deployment occurred.
Edge Routing and Indexation Mechanics: Server-Side Page Clustering Architecture
Client-side A/B testing platforms like Optimizely or VWO are fundamentally disqualified from technical SEO experimentation. Injecting DOM modifications via client-side JavaScript causes severe Cumulative Layout Shift (CLS), inflates Largest Contentful Paint (LCP), and frequently results in Googlebot indexing the pre-injection fallback state due to deferred web-rendering service (WRS) execution. To guarantee that crawlers encounter identical DOM trees as real users without triggering cloaking penalties, split testing must execute entirely server-side at the CDN or reverse-proxy edge layer.
Edge execution platforms—such as Cloudflare Workers, Fastly Compute, or Next.js App Router Middleware—evaluate incoming request paths against a deterministic clustering manifest. When Googlebot or an end-user requests a target URL, the edge worker checks whether the specific entity belongs to the control or variant set. The variant modification (such as optimized schema markup, altered header hierarchies, or internal linking modules) is executed prior to stream delivery to the client. This architecture guarantees a sub-10ms TTFB delta and maintains uniform DOM delivery across both HTTP crawlers and browser engines.
Maintaining rigorous search engine parity requires absolute structural invariants across the cohort partitions:
- Canonical Integrity: Every page within both the control and variant groups must self-canonicalize. Never employ cross-group canonical tags to split test, as this explicitly signals duplicate content consolidation and invalidates crawl frequency.
- Internal Link Weighting: Automated internal linking modules must not bias the variant group. Invariant internal PageRank distribution must be enforced across all test cohorts to prevent confounding link equity with on-page technical changes.
- Crawl Velocity Normalization: Monitor edge-layer access logs in real time to verify that Googlebot crawl request distribution remains proportional across control and variant buckets post-deployment.
Production Runbook: Building an Automated SEO Split Testing Engine with BigQuery and Edge Workers
Execute the following pipeline to construct an automated, edge-routed SEO experimentation framework backed by BigQuery Search Console bulk export telemetry.
Step 1: Ingest and Match Synthetic Control Cohorts
Run the following BigQuery SQL script to aggregate baseline telemetry (pre-intervention period) across candidate URL cohorts, computing rolling averages to extract matched pairs with identical click-and-impression distributions.
WITH PreInterventionMetrics AS (
  SELECT
    data_date,
    url,
    SUM(impressions) AS daily_impressions,
    SUM(clicks) AS daily_clicks,
    SAFE_DIVIDE(SUM(clicks), SUM(impressions)) AS daily_ctr
  FROM
    `enterprise-analytics.searchconsole.searchdata_url_impression`
  WHERE
    data_date BETWEEN DATE_SUB(CURRENT_DATE(), INTERVAL 60 DAY)
                  AND DATE_SUB(CURRENT_DATE(), INTERVAL 30 DAY)
    AND url LIKE 'https://example.com/integrations/%'
  GROUP BY
    1, 2
),
URLBaselines AS (
  SELECT
    url,
    AVG(daily_impressions) AS mean_impressions,
    STDDEV(daily_impressions) AS std_impressions,
    AVG(daily_clicks) AS mean_clicks,
    COUNT(DISTINCT data_date) AS active_days
  FROM
    PreInterventionMetrics
  GROUP BY
    1
  HAVING
    active_days >= 28
)
SELECT
  url,
  mean_impressions,
  mean_clicks,
  NTILE(2) OVER(ORDER BY mean_impressions DESC, mean_clicks DESC) AS assigned_cohort
FROM
  URLBaselines;
Step 2: Deploy Edge Routing Worker for Variant Injection
Deploy a Cloudflare Worker interceptor targeting the /integrations/* directory. This script reads the compiled experimentation manifest from KV storage, injects modified JSON-LD schema into the HTML stream on variant pages, and emits experimentation headers for downstream telemetry collection.
import { HTMLRewriter } from '@cloudflare/workers-types';

interface Env {
  EXPERIMENT_MANIFEST: KVNamespace;
}

export default {
  async fetch(request: Request, env: Env): Promise<Response> {
    const url = new URL(request.url);
    const pathname = url.pathname;

    // Verify cohort classification from Edge KV
    const cohort = await env.EXPERIMENT_MANIFEST.get(pathname);

    const response = await fetch(request);

    // Pass-through control group or unassigned paths
    if (cohort !== 'variant') {
      const newHeaders = new Headers(response.headers);
      newHeaders.set('X-SEO-Experiment', 'control');
      return new Response(response.body, {
        status: response.status,
        headers: newHeaders,
      });
    }

    // Inject upgraded SoftwareApplication JSON-LD into Variant HTML
    const rewriter = new HTMLRewriter().on('head', {
      element(element) {
        const schema = {
          '@context': 'https://schema.org',
          '@type': 'SoftwareApplication',
          'operatingSystem': 'Cloud',
          'applicationCategory': 'BusinessApplication'
        };
        element.append(
          `<script type="application/ld+json">${JSON.stringify(schema)}</script>`,
          { html: true }
        );
      }
    });

    const transformedResponse = rewriter.transform(response);
    transformedResponse.headers.set('X-SEO-Experiment', 'variant');
    return transformedResponse;
  }
};
Step 3: Compute Counterfactual Uplift
Following a 30-day intervention window, extract daily impression totals for the control and variant groups. Run the R or Python CausalImpact library using Markov Chain Monte Carlo (MCMC) sampling. The control group serves as the predictive covariate to generate the counterfactual projection, outputting the absolute lift, relative percentage lift, and the posterior probability that the observed gain is statistically distinct from null hypothesis noise (p < 0.05).
Enterprise MRR Impact: De-risking Programmatic SEO and Lowering Blended CAC
Deploying uncontrolled template modifications across hundreds of thousands of programmatic landing pages represents massive financial risk for enterprise B2B organizations. A flawed internal link structure or bad structured data roll-out can trigger sitewide algorithm suppression, directly deteriorating high-intent search visibility and crashing pipeline generation. By running edge-controlled, synthetic-control experiments on 5% of candidate subdirectories, engineering teams validate whether technical modifications increase crawl efficiency and conversion volume before releasing sitewide, protecting millions in organic-attributed Annual Recurring Revenue (ARR).
Furthermore, statistically sound SEO split testing eliminates reliance on paid search arbitrage. By isolating true organic rank drivers, acquisition teams can systematically optimize high-conversion landing page templates to outrank competitor aggregators without deploying incremental engineering cycles on neutral or negative tactics. By tying variant clusters directly to pipeline data—using server-side tracking pipelines through GA4 Measurement Protocol and BigQuery—growth leaders compute the exact CAC reduction achieved per algorithmic test, transforming the SEO backlog into an empirical, revenue-generating product roadmap.
System Telemetry Source: Original Engineering Report
Related Growth Blueprints
All Playbooks →Want this working inside your business?
Whether you're a founder fixing tracking leaks or a team scaling SEO and AI workflows, share your site and bottleneck for a clear diagnostic within 48 hours.