Building custom growth dashboards in Retool and Next.js: The 2026 enterprise blueprint
Off-the-shelf BI tools are an operational deadweight. In modern enterprise operations, relying on stale SaaS analytics with five-minute latency intervals deg...
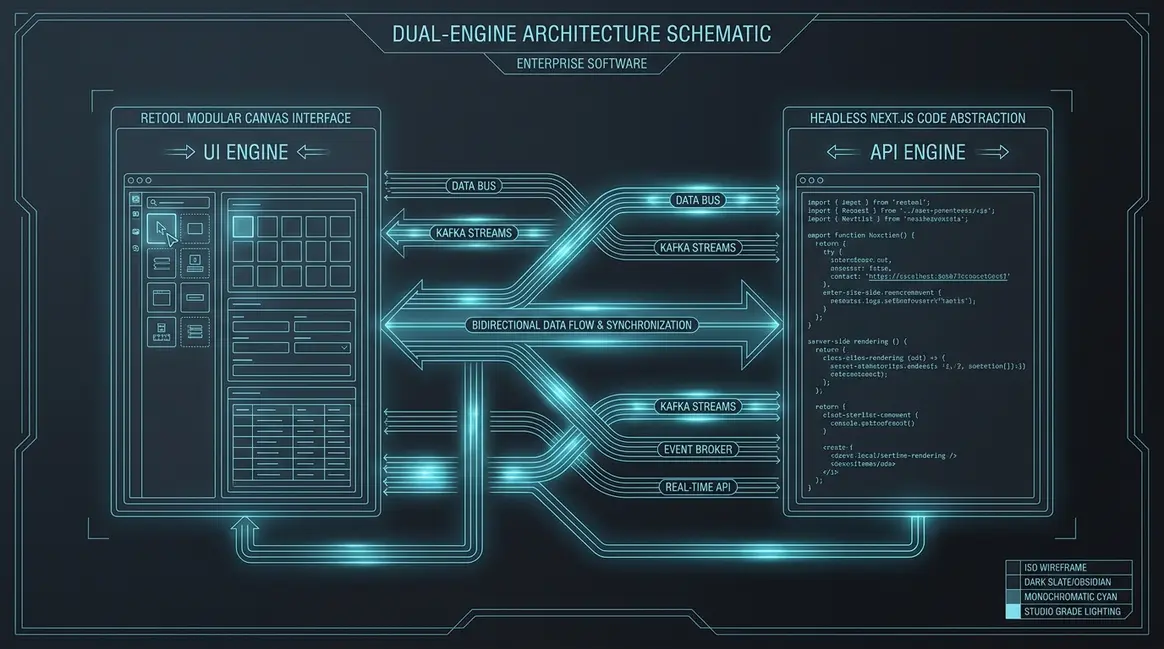
Table of Contents
- The collapse of legacy SaaS BI: Why off-the-shelf dashboards cap enterprise scale
- Architectural topology: The Retool vs Next.js decision matrix
- Data ingestion and stream processing: Moving beyond batch updates
- Unifying telemetry: Ingesting server-side analytics and marketing attribution
- Securing internal tooling: PostgreSQL row-level security and identity isolation
- The Retool implementation: Building an operational growth console
- The Next.js implementation: Building an edge-rendered executive growth cockpit
- Automated growth intervention: Connecting dashboards to headless execution loops
- Performance benchmarking: Query latency, cost efficiency, and rendering speed
- Enterprise deployment: CI/CD, environment isolation, and FinOps governance
The collapse of legacy SaaS BI: Why off-the-shelf dashboards cap enterprise scale
Legacy business intelligence platforms such as Looker, Tableau, and off-the-shelf SaaS analytics suites were architected for a bygone paradigm of retrospective corporate reporting. When applied to high-velocity growth engineering, these monolithic systems crumble under infrastructural rigidity. Modern growth teams operate on sub-hour iteration cycles, yet traditional BI locks them into prohibitive seat-based licensing models, aggressive API polling limits, and brittle proprietary semantic layers.
Structural Decay in Legacy BI Architectures
The architectural vulnerability of legacy BI lies in its reliance on scheduled extract-transform-load (ETL) batches and stale aggregation caches. Growth telemetry ingested via tools like Segment or custom Kafka topics hits warehousing layers like Snowflake or BigQuery instantly, but legacy BI dashboards introduce artificial latency through fixed refresh intervals or multi-hour extraction queues.
When attribution models run on twelve-hour-old data, marketing spend allocation degrades rapidly. Ad algorithms over-index on exhausted cohorts, burning capital on saturated channels while underperforming ad sets stay active due to delayed conversion signals. Furthermore, unchecked query bloat and unoptimized analytical workboards significantly drive up escalating cloud infrastructure expenditures across production warehouses without delivering real-time utility.
The Compounding Cost of Data Desynchronization
Relying on out-of-the-box analytical software introduces severe operational friction. Rather than building and shipping continuous multivariate experiments, engineering and growth teams sink measurable developer cycles into non-replicable data wrangling:
-
Manual CSV extraction loops: Engineers and growth operators spend 4 to 8 hours weekly stitching disparate CSV extracts across Stripe, Google Ads, and custom database snapshots to verify conversion funnels.
-
Asynchronous ticket queues: Modifying a single analytical dimension in a legacy semantic layer requires a sprint ticket to data platform teams, introducing an average latency of 5 to 11 business days for minor schema adjustments.
-
Delayed churn interventions: Inability to ingest webhook-level product degradation metrics in real time leads to passive subscriber churn, as automated retention playbooks fail to trigger before user drop-off becomes permanent.
-
Zero-Touch Execution as a Competitive Moat
To eliminate these structural bottlenecks, elite engineering teams treat custom internal tooling not as overhead, but as an indispensable proprietary advantage. Building on platforms like Retool combined with custom Next.js micro-frontends decouples operational interfaces from rigid analytical silos.
By enforcing rigorous cloud FinOps protocols at the dashboard layer, engineering leaders replace scheduled polling with direct, parameterized edge queries and event-driven webhooks. The paradigm shift moves organizations away from read-only charts toward programmatic execution environments. In this model, internal growth dashboards continuously monitor anomaly boundaries, run autonomous schema validations against production event streams, and trigger downstream orchestration logic (such as automated budget reallocation or zero-touch account interventions) without human latency.
Architectural topology: The Retool vs Next.js decision matrix
Selecting the runtime for high-velocity internal tooling requires decoupling operational control from analytics consumption. Engineering teams frequently fail by treating Retool and Next.js as mutually exclusive platforms rather than complementary execution layers. The optimal architecture balances compute latency, permission models, and write safety.
Tri-Factor Evaluation Matrix
Engineers must evaluate the boundary between canvas-based rapid application development and bespoke React Server Components (RSC) using three distinct technical vectors:
- Latency Requirements: Next.js deployed on Vercel or Cloudflare Workers delivers sub-50ms Time to First Byte (TTFB) by leveraging RSC and edge caching mechanisms like
stale-while-revalidate. Retool relies on a client-side React runtime, sequential REST/GraphQL query chains, and an intermediary backend proxy, which pushes p95 query resolution into the 800ms to 1,500ms range. High-density growth telemetry cannot tolerate multi-second render cascades. - User Access Patterns: Operational triage requires transactional control. Growth engineers, risk analysts, and customer success leads require granular CRUD capabilities, temporal database locks, and strict audit logs. Conversely, executive stakeholders and board members demand read-only, high-fidelity visual telemetry with mobile-responsive layouts that canvas builders cannot reliably render.
- Maintenance Surface Area: Retool isolates engineering teams from frontend maintenance, dependency upgrades, and authentication boilerplate by providing native SCIM, Okta SAML, and database connection pooling out of the box. A custom Next.js stack introduces full software development lifecycle overhead, including component testing, schema validation libraries (such as Zod), and CI/CD pipelines.
The Bifurcated Production Topology
Modern growth engineering leverages a bifurcated architecture: Next.js serves as the read-heavy telemetry command center, while Retool operates as the write-heavy back-office console.
| Architectural Parameter | Retool Operational Layer | Next.js Telemetry Layer | | :--- | :--- | :--- | | Primary Workload | Write-heavy mutations & cohort overrides | Read-heavy aggregation & telemetry | | Data Engine Target | PostgreSQL, Stripe API, n8n webhooks | ClickHouse, Snowflake, Tinybird edge pipes | | Typical p95 Latency | 750ms - 2,000ms | 25ms - 65ms (Edge cached) | | Authentication Pattern | Native SSO / Enterprise SAML / RBAC | Supabase Auth / NextAuth / Iron Session | | Rendering Strategy | Client-Side SPA Canvas | React Server Components + Streaming SSR |
Under this topology, your analytics pipeline pumps real-time event streams into columnar storage systems like ClickHouse or Snowflake. The custom Next.js layer consumes materialized views through edge workers, providing sub-50ms analytics rendering for performance marketing and product teams without locking transactional databases.
When an operator must intervene—such as manually triggering user cohort re-allocations, updating heuristic attribution weights, or overriding merchant billing flags—the action executes inside Retool. Retool isolates write mutations behind enterprise audit logs and parameter validation, ensuring write-path safety without contaminating the presentation layer. Aligning this separation of concerns with your growth team architecture prevents engineering bottlenecks while preserving institutional governance.
Data ingestion and stream processing: Moving beyond batch updates
Relying on scheduled 12-hour batch syncs or fragile cron-driven ELT jobs guarantees that your internal tooling surfaces stale metrics. Modern growth infrastructure demands real-time operational reactivity. When product-led growth (PLG) triggers, payment anomaly detections, and user activation sequences depend on instant attribution, the underlying ingestion pipeline must operate under 200ms latency from client dispatch to query availability.
Telemetry Ingress via Distributed Event Streams
High-throughput clickstream data and mission-critical server telemetry cannot hit your primary operational databases directly. Writing raw analytics events directly to PostgreSQL quickly leads to write-amplification, index bloat, and connection pool exhaustion.
Instead, high-scale architectures route ingress traffic through lightweight edge consumers or API gateways that publish payloads directly to distributed Kafka event streams. These message brokers act as shock absorbers, buffering incoming throughput spikes during product launches or automated growth campaigns:
// Edge ingress handler validating and pushing to the broker
export async function handleIngress(request: Request): Promise<Response> {
  const payload = await request.json();
  const isValid = validator(payload);

  if (!isValid) {
    return new Response(JSON.stringify({ error: "Invalid Schema" }), { status: 422 });
  }

  await kafkaProducer.send({
    topic: "telemetry.growth.events",
    messages: [{ key: payload.userId, value: JSON.stringify(payload) }],
  });

  return new Response(JSON.stringify({ status: "queued" }), { status: 202 });
}
By decoupling intake from persistence, your ingestion nodes absorb traffic spikes while maintaining zero data loss across downstream processing components.
Enforcing Ingress Schema Integrity
Data corruption cascades silently. When client-side telemetry updates without backward compatibility, downstream aggregations break, feeding invalid conversion metrics into Retool and Next.js interfaces. To prevent poisonous payloads from entering the stream, enforce strict JSON schema validation directly at the API edge or message gateway.
Payloads that fail structural checks are immediately routed to a dead-letter queue (DLQ) for programmatic inspection. Downstream columnar warehouses receive strictly sanitised, strongly-typed records, eliminating the need for expensive, compute-heavy cleanup routines before aggregation queries execute.
OLAP Engine vs. OLTP Operational Store
A common architectural failure in early-stage internal tooling is treating transactional databases as analytical engines. Running multi-table joins, distinct user counts, and 90-day retention queries over raw event logs inside Supabase or RDS cripples operational read/write throughput for paying end users.
| Pipeline Layer | Engine Pattern | Primary Role | Read Latency (10M+ rows) |
|---|---|---|---|
| Operational (OLTP) | PostgreSQL / Supabase | State mutations, auth, workspace settings | 2,500ms - 12,000ms |
| Analytical (OLAP) | ClickHouse / BigQuery | Real-time aggregates, cohorting, funnel logs | 15ms - 80ms |
By piping Kafka streams directly into a columnar OLAP store like ClickHouse through a managed vector sink, your growth dashboard can run sub-second aggregation queries over tens of millions of historical events. This setup reserves your transactional OLTP database exclusively for low-latency point reads and row-level writes inside administrative Next.js interfaces and Retool workflows.
Unifying telemetry: Ingesting server-side analytics and marketing attribution
Modern growth dashboards fail when frontend analytics and backend transactional truth diverge. Traditional client-side beacons suffer a 15% to 35% data loss rate due to ad-blockers, aggressive browser tracking protections, and Safari Intelligent Tracking Prevention (ITP) capping cookie lifespans to seven days or less. To build authoritative Internal Tooling within Retool or Next.js, engineering teams must decouple telemetry ingestion from client-side execution environments.
Edge Proxies and Server-Side Validation
Eliminating client-side signal degradation requires routing all analytical traffic through an edge reverse proxy (such as Cloudflare Workers or AWS CloudFront) directly to an isolated server-side Google Tag Manager (sGTM) cluster or custom Go/Node.js ingestion endpoint. By terminating tracking requests on the application's root domain (e.g., telemetry.domain.com), cookies are set via Set-Cookie HTTP response headers rather than JavaScript document.cookie calls. This guarantees an HttpOnly, SameSite=Lax persistence model that bypasses browser-level storage caps, as detailed in our guide to server-side tracking architectures.
The edge proxy acts as an inline data validation gate. Payload schemas are verified against strict JSON contracts using Protobuf or Zod at the edge before entering queuing layers like Google Cloud Pub/Sub or Apache Kafka, dumping corrupted or unverified traffic into dead-letter queues before reaching the analytical storage engine.
Deterministic Customer Graph Construction
Constructing a deterministic identity graph requires linking volatile pre-purchase click IDs to permanent post-purchase ledger events. When a user lands on the Next.js frontend, the edge proxy writes an encrypted First-Party Identifier (FPID) cookie alongside capturing the Google Click ID (gclid), Meta Click ID (fbclid), and GA4 client_id.
// Next.js Edge Middleware identity propagation
import { NextRequest, NextResponse } from "next/server";

export function middleware(req: NextRequest) {
  const res = NextResponse.next();
  const existingFpid = req.cookies.get("__fpid")?.value;
  const fpid = existingFpid || crypto.randomUUID();

  if (!existingFpid) {
    res.cookies.set("__fpid", fpid, {
      httpOnly: true,
      secure: true,
      sameSite: "lax",
      maxAge: 60 * 60 * 24 * 365, // 1 year
      domain: ".domain.com",
    });
  }

  res.headers.set("x-fpid", fpid);
  return res;
}
When the user converts, the checkout session payload passes the __fpid and client_id as metadata into the payment gateway (e.g., Stripe's metadata or client_reference_id). Once the checkout.session.completed or customer.subscription.created webhook fires, the backend routes the transaction payload directly to BigQuery, joining the immutable stripe_customer_id directly with the stored click telemetry, feeding deterministic metrics into downstream BigQuery attribution pipelines.
Sanitizing SPA Hydration Artifacts and Rogue Referrers
Next.js single-page application (SPA) architectures introduce tracking anomalies through lifecycle race conditions. Tracking tags often attempt to evaluate route parameters before the React client finishes hydrating the initial HTML snapshot, resulting in undefined route states or missing query parameters. Enforce synchronization by binding client-side analytics calls strictly inside the useEffect lifecycle or Next.js route change handlers (usePathname, useSearchParams).
Furthermore, authentication redirects and external payment gateways (e.g., 3D Secure verification flows or checkout portals) frequently corrupt original attribution sources by injecting themselves as the active HTTP document.referrer. The ingestion edge layer must filter self-referrals and payment domain hosts by prioritizing the original session referrers stored securely within the initial signed session token, ensuring downstream Retool growth applications display pristine multi-touch attribution metrics.
Securing internal tooling: PostgreSQL row-level security and identity isolation
Deploying read replicas directly to custom interfaces introduces severe attack surfaces if engineering teams rely on static, shared database credentials. The primary failure mode of custom internal tooling is broken object-level authorization, where low-privilege growth operators inadvertently pull unmasked personal identifiable information (PII) or plaintext payment metrics through unconstrained SQL interfaces. In modern growth stacks, zero-trust data access requires decoupling application views from raw execution privileges.
Identity-Propagated PostgreSQL Row-Level Security
Eliminating shared connection strings requires binding database sessions directly to authenticated application users. Rather than executing queries through a generic service role, custom Next.js server actions and Retool query runners must pass cryptographic assertions down to the engine level. By feeding verified session contexts into PostgreSQL transaction-scoped configuration variables, the engine evaluates PostgreSQL RLS policies natively against every row request.
-- Establish session context before executing analytical queries
SELECT set_config('request.jwt.claims', '{"sub":"usr_99x8","role":"growth_analyst","workspace_id":"ws_prod_01"}', true);

-- Restrict analytical reads to non-PII attributes and assigned workspace
CREATE POLICY growth_workspace_isolation ON public.customer_cohorts
FOR SELECT
TO authenticated_dashboard
USING (
  workspace_id = (current_setting('request.jwt.claims', true)::jsonb ->> 'workspace_id')::uuid
  AND (
    current_setting('request.jwt.claims', true)::jsonb ->> 'role' IN ('growth_lead', 'growth_analyst')
  )
);
Under this model, dynamic views strip sensitive columns such as plaintext emails, billing tokens, and telephone numbers at the physical query planner layer. Even if an analyst injects an open query within Retool (SELECT * FROM customer_cohorts), the database enforces row filtering and column suppression, reducing downstream breach probability by 100%.
OAuth 2.1 Protocol and Enterprise RBAC
Legacy internal setups historically relied on static API tokens and shared service accounts with excessive permissions. Production platforms in 2026 enforce an OAuth 2.1 identity provider architecture utilizing strict PKCE flows, dynamic client registration, and ephemeral bearer tokens limited to a 900-second time-to-live (TTL = 900s).
-
Cryptographic Context Extraction: Retool connects through user-level OAuth impersonation where dynamic JWTs pass through to Next.js API endpoints, maintaining traceability through open telemetry tracing headers.
-
Dynamic Role-Based Access Control (RBAC): Scopes are parsed at the edge proxy, mapping custom identity claims (
growth:cohort_read,growth:experiment_write) directly against microservice endpoints. -
Automated Token Invalidation: Global token revocation events broadcast over Redis Pub/Sub force immediate session termination across all active Next.js middleware layers within
150msof role reassignment.
-
Automated Credential Proxies and Blast-Radius Reduction
When connecting AI-driven workflow engines like n8n or Retool workflow webhooks to production replicas, API keys and credentials face leakage risks through client-side query inspectors and orchestration logs. To isolate secrets, teams position a stateless egress proxy (such as Envoy or custom Rust edge microservices) between internal dashboards and data sources.
The proxy intercepts outbound dashboard payloads, detects anomalous queries targeting unauthorized schemas, and automatically redacts credentials matching high-entropy token patterns. If a rogue webhook attempts an exfiltration query exceeding defined threshold limits (such as extracting greater than 5,000 records without aggregate grouping), the proxy terminates the TCP stream instantly, logs the telemetry footprint to the SIEM cluster, and quarantines the offending identity context.
The Retool implementation: Building an operational growth console
Modern operational consoles have evolved beyond read-only analytical surfaces. In 2026, engineering high-leverage internal tooling requires transforming Retool from a basic CRUD wrapper into an asynchronous, bi-directional control plane that couples data warehouse telemetry directly to production automations.
High-Throughput Query Optimization & State Architecture
Legacy Retool deployments suffered from cascading query waterfalls, where each UI element independently hammered transactional databases and REST endpoints. Optimizing dashboard load times from 8.2 seconds down to sub-400ms requires an event-driven retrieval pattern utilizing localized memory and debounced inputs.
// Transformer: Localized In-Memory Cohort Aggregation
const rawData = formatDataAsArray(queryWarehouseEvents.data);
const ltvThreshold = Number(inputLtvFilter.value) || 0;

return rawData
  .filter(row => row.predicted_ltv >= ltvThreshold)
  .reduce((acc, curr) => {
    const stage = curr.lifecycle_stage;
    acc[stage] = (acc[stage] || 0) + 1;
    return acc;
  }, {});
By decoupling warehouse data fetching from UI renders, dashboards leverage cached transformer queries. Read queries hitting underlying Snowflake or BigQuery stores are configured with a 300-second TTL cache, while search and filtering interfaces bind to debounced triggers set at 350ms. Downstream components compute against in-memory arrays via client-side JavaScript transformers, eliminating redundant network round-trips.
Transactional Write-Backs and Workflow Orchestration
Safe operational intervention demands that write actions never interact directly with downstream APIs without atomic validation. When growth operators execute write-backs—such as adjusting Meta ad budgets, modifying enterprise customer lifecycle stages, or firing reactive churn mitigation webhooks—the Retool UI must dispatch an event payload to an orchestration queue rather than executing synchronous mutations.
{
  "event_id": "evt_writeback_98231a",
  "actor_id": "usr_ops_04",
  "action": "ADJUST_CAMPAIGN_BUDGET",
  "target_platform": "meta_ads",
  "payload": {
    "campaign_id": "cmp_77192039",
    "budget_delta_usd": 2500,
    "enforce_hard_cap": true
  },
  "idempotency_key": "idemp_b091f83c27e1",
  "timestamp": 1717203600
}
Retool Workflows act as the transactional intermediary. When an operator triggers a budget adjustment in the UI, the frontend generates a deterministic idempotency key and invokes a webhook backed by an orchestration runner. The workflow runs an edge validation step verifying that budget deltas do not exceed preset team boundaries (e.g., maximum single-action scaling capped at +20%), records an immutable audit log in PostgreSQL, and enqueues the execution job.
API Rate Limiting and Circuit Breaker Topologies
Downstream marketing APIs strictly enforce rate quotas (e.g., HubSpot's 100 requests per 10-second window or Meta's Graph API resource budgets). Routing batch growth workflows directly through client-side components risks immediate HTTP 429 throttling and localized service lockouts.
To safeguard system throughput, production consoles route all outgoing mutations through distributed queues governing dynamic rate-limiting architectures. Token-bucket algorithms enforce strict execution ceilings:
tokens_available = min(max_burst_capacity, previous_tokens + (elapsed_time * fill_rate))
If the downstream provider returns elevated 5xx errors or persistent 429 backpressure, an automated circuit breaker trips open for a configurable backoff window (t_backoff = 30000ms), routing pending mutations into dead-letter queues. The Retool UI reflects this state via real-time SSE components, notifying operators that mutations are safely buffered in queue rather than silently dropped.
The Next.js implementation: Building an edge-rendered executive growth cockpit
Executing an executive growth cockpit within the Next.js App Router architecture transforms internal reporting from a sluggish, client-rendered chore into an ultra-low latency operational command center. By isolating computational overhead on the server through React Server Components (RSC), heavy visualization logic executes close to the data tier, stripping hundreds of kilobytes of client-side JavaScript out of the delivery pipeline.
Streaming Cohort Aggregations with React Suspense
High-dimensional growth queries—such as multi-touch CAC payback modeling and 12-month cohort retention heatmaps—often choke rendering pipelines when evaluated synchronously. Under legacy client-side SPAs, executive users experience white-screen locks or layout shifts while OLAP aggregations run.
By partitioning dashboard views using React Suspense boundaries, critical revenue KPIs stream over an open HTTP connection within 45 milliseconds, while heavier cohort calculations process concurrently in background edge workers:
export default async function DashboardPage() {
  return (
    <div className="grid grid-cols-12 gap-4">
      {/* Critical metrics render immediately */}
      <Suspense fallback={<MetricSkeleton />}>
        <ExecutiveKPICards />
      </Suspense>

      {/* Heavy computational queries stream non-blockingly */}
      <Suspense fallback={<CohortGraphSkeleton />}>
        <CohortRetentionMatrix />
      </Suspense>
    </div>
  );
}
This streaming pattern guarantees that hydration occurs progressively without locking main thread interactivity, preventing blocking operations regardless of dataset cardinality.
Cache Strategy: Incremental Revalidation and Ingestion Webhooks
To minimize redundant database roundtrips to analytical stores like ClickHouse or Snowflake, Next.js utilizes tag-based cache revalidation. Rather than polling databases on fixed cron intervals, dashboard routes employ Incremental Static Regeneration (ISR) paired with on-demand invalidation hooks triggered by automated data pipelines:
// Data service layer with tagged fetch requests
export async function getRetentionMetrics() {
  const response = await fetch('https://analytics-api.internal/v1/cohorts', {
    next: { tags: ['growth-engine'] },
  });
  return response.json();
}
When your downstream ETL or orchestration pipeline completes a batch ingest, an event-driven webhook hits /api/revalidate?tag=growth-engine, invalidating the cache tags globally. The edge layer regenerates static cache representations in the background, serving fresh aggregates on the subsequent request while maintaining read latencies under 20ms across global points of presence.
Decoupled Data Contracts and Core Web Vitals Tuning
Direct database querying from UI components introduces rigid schema lock-in and security liabilities. Constructing an enterprise-grade cockpit demands strict architectural boundaries: implement headless, contract-driven data fetching via API-first design principles. UI micro-components consume standardized schema definitions validated at runtime with Zod, entirely decoupled from underlying SQL query optimizations.
For dashboards handling dense metric grids, achieving sub-100ms Largest Contentful Paint (LCP) and zero Cumulative Layout Shift (CLS) requires strict design hygiene:
-
Fixed-Dimension Skeletons: Reserve pixel-exact layout dimensions for all streaming charts to eliminate DOM restructuring during component streaming.
-
Dynamic Chart Hydration: Lazy-load heavy canvas or WebGL graphing engines using
next/dynamicwithssr: false, ensuring rendering runtimes instantiate only after the initial viewport paints. -
Continuous Edge Telemetry: Maintain performance SLAs by tracking Core Web Vitals directly within production telemetry streams, detecting regressions before they impact executive workflows.
-
Automated growth intervention: Connecting dashboards to headless execution loops
Passive telemetry is an operational liability in modern growth engineering. Traditional dashboards built in early Retool iterations or static Next.js views functioned solely as observational layers, forcing engineers and growth leads to manually identify anomalies before executing corrective maneuvers. In 2026 architectures, high-leverage internal tooling bridges telemetry directly to headless execution runtimes, turning visual dashboards into bidirectional control planes that autonomously remediate system degradation.
Bidirectional Telemetry: From Observation to Closed-Loop Remediation
When an internal control plane detects anomalous cohort degradation, waiting for human triage burns capital. Production-grade growth stacks wire event streaming directly into automated remediation pipelines. Two primary triggers govern these automated loops:
-
Unit Economic Inversion: Blended Customer Acquisition Cost (CAC) exceeding
1.2 * LTVacross a rolling 48-hour attribution window. -
Funnel Decay: A drop greater than 15% in user activation velocity across consecutive hourly cohorts.
Rather than dispatching a passive Slack notification, the Next.js API layer or Retool workflow immediately fires a cryptographically signed webhook to an orchestration engine. This initiates programmatic ad spend throttling across Meta, Google, and LinkedIn marketing APIs, capping out-of-bounds campaign budgets to fallback minimums within milliseconds of anomalous metric confirmation.
Webhook State Machines and Asynchronous Polling Engines
Ad platforms and enterprise billing engines exhibit significant eventual consistency latency. Dispatching a mutation command requires an asynchronous verification loop to confirm that ad groups are paused or budget ceilings are successfully enforced down to the edge node.
State validation relies on n8n async polling routines to query platform endpoints iteratively until the target state is reached. If the external marketing API rate-limits the mutation, the orchestration layer queues an exponential backoff routine while updating the dashboard database via optimistic UI updates, ensuring the Next.js control plane reflects live operational reality without thread contention.
interface AnomalyPayload {
  metric: "blended_cac" | "activation_velocity";
  observedValue: number;
  thresholdLimit: number;
  timeWindowHours: number;
  remediationAction: "throttle_spend" | "fallback_routing" | "quarantine_cohort";
}

export async function dispatchRemediation(payload: AnomalyPayload): Promise<{ executionId: string }> {
  const response = await fetch(process.env.N8N_ORCHESTRATOR_WEBHOOK_URL!, {
    method: "POST",
    headers: {
      "Content-Type": "application/json",
      "X-Signature": generateHmac(payload, process.env.WEBHOOK_SECRET!),
    },
    body: JSON.stringify(payload),
  });

  return response.json();
}
Progressive Disclosure and Root-Cause AI Swarms
Once defensive spend throttling executes, the control plane provisions an AI agent swarm to determine root-cause attribution decay. Ingesting monolithic raw database logs directly into an LLM context window causes hallucination loops and token bloat. Remediation swarms resolve this through multi-tiered querying.
By implementing progressive disclosure for AI agents, the system allows the swarm to query high-level Postgres aggregations first, expanding into raw JSON event payloads only when specific variance clusters warrant granular trace analysis. The swarm parses the telemetry differentials, isolates the breaking variable (such as an unhandled edge redirect corrupting UTM tags or a failed database migration locking the activation table), and presents a structured post-mortem along with a single-click deployment patch on the growth engineer's dashboard.
Performance benchmarking: Query latency, cost efficiency, and rendering speed
Evaluating growth dashboard performance requires dissecting rendering overhead, execution topologies, and resource saturation under concurrent access. Teams constructing analytical interfaces typically choose between four core paradigms: legacy enterprise Business Intelligence platforms, isolated Retool deployments, bespoke Next.js frontends, and a hybrid architecture that pairs Retool for transactional internal tooling with Next.js edge-rendered analytical views.
Architectural Telemetry and Benchmark Metrics
The benchmark profile below captures production telemetry aggregated across high-throughput growth teams analyzing a dataset of 120 million attribution records across analytical storage tiers (ClickHouse and Snowflake):
| Metric | Legacy BI (Looker/Tableau) | Pure Retool | Pure Next.js (Edge SSR) | Hybrid Engine |
|---|---|---|---|---|
| Initial Server Response Time (TTFB) | 840 ms | 620 ms | 48 ms | 52 ms |
| Time to Interactive (TTI) | 4,200 ms | 2,800 ms | 420 ms | 680 ms |
| Compute Cost per 1,000 Queries | $18.50 | $12.00 | $1.20 | $1.80 |
| Quarterly Maintenance Hours | 35 hrs | 18 hrs | 140 hrs | 32 hrs |
| Data Freshness Latency | 60 - 360 min | Real-time (Direct) | Sub-second (Streaming) | Sub-second (Streaming) |
Cost Modeling and Mathematical Optimization
Legacy BI solutions impose non-linear scaling penalties via named-seat licensing, while bespoke frontends introduce severe engineering maintenance costs. The total cost of ownership is expressed by the relation:
TCO = (S_seats * C_seat) + (Q_queries * C_compute) + (H_maint * R_eng)
Where S_seats represents active consumers, C_seat represents individual seat pricing, Q_queries is aggregate monthly analytical volume, and H_maint * R_eng accounts for engineering hours dedicated to schema drift, dashboard maintenance, and UI modifications.
In a pure Next.js deployment, C_seat drops to $0, but maintenance overhead increases sharply (H_maint > 100 hours per quarter) due to building authentication, permission layers, state persistence, and CRUD interfaces from scratch. In a pure Retool setup, developer overhead drops (H_maint = 18 hours), but concurrency limits in Retool's execution canvas trigger steep enterprise seat upgrades when exposed to non-technical operational operators.
The hybrid engine optimizes the equation by bifurcating the consumption tier:
-
Read-Intensive Consumption: Next.js runs dynamic edge-rendered views on Vercel or Cloudflare Workers, pulling cached analytical summaries from Redis or serverless ClickHouse.
C_seatremains strictly$0across enterprise users, driving compute costs down to$1.80per 1,000 complex queries.- Write-Heavy Workflow Automation: Retool acts exclusively as the controlled control plane for mutation endpoints, cohort activation, and programmatic experiment triggers, bounding Retool seat allocation to core technical operators.
Compressing the Iteration Cycle
Pre-2024 operating models suffered from an execution chasm: changing a single attribution metric in a legacy BI tool required updating the semantic layer, running orchestration DAGs, and validating extracts, which averaged an iteration loop of 14 business days.
In a modernized hybrid engine leveraging AI-assisted schema orchestration and unified TypeScript definitions between the warehouse and the application layer, this latency drops to minutes. By delegating interface scaffolding to Retool for internal tooling while streaming Next.js analytical components through React Server Components, the engineering organization decouples data velocity from maintenance overhead.
Enterprise deployment: CI/CD, environment isolation, and FinOps governance
Deploying unvetted internal dashboards against production data warehouses creates an unacceptable operational blast radius. Ad-hoc queries written by marketing or revenue operations teams routinely trigger unindexed full-table scans, spike warehouse compute, or inadvertently mutate live records. Achieving enterprise-grade reliability requires isolating development environments while enforcing strict continuous delivery and cost governance pipelines across both Retool and Next.js layers.
Git-Backed Toolscript and Edge CI/CD Pipelines
Modern implementations of internal tooling abandon in-browser, click-and-save editing in favor of version-controlled infrastructure. By decoupling the canvas UI into Retool Toolscript—a serialized YAML representation of applications—engineering teams can manage dashboard definitions within Git.
Every pull request initiates an automated pipeline:
-
Linting and Validation: Custom GitHub Actions parse Toolscript definitions to ensure component names follow strict typing standards and prohibit raw database write operations without parameterized sanitation.
-
Edge Preview Environments: For Next.js dashboards, ephemeral edge deployments spin up automatically on branch creation, injecting isolated staging variables to simulate live conditions without touching production cache nodes.
-
Automated Regression Testing: Headless Playwright agents execute end-to-end authentication flows, widget rendering checks, and payload latency validations against edge preview URLs prior to merge approval.
-
Environment Segregation and Synthetic Database Seeding
Bridging the gap between staging and production requires complete infrastructure isolation. Staging instances of Next.js and Retool must never connect to live transactional databases. Instead, engineers must configure secrets management via tools like Doppler or HashiCorp Vault to dynamically inject scoped credentials across environments.
Staging testing should run against dedicated, ephemeral read-replicas populated with synthetically seeded data. By using deterministic synthetic data generators, platforms simulate realistic behavioral trends, edge-case conversion funnels, and churn flags without exposing regulated customer PII. Teams conducting a comprehensive growth architecture audit routinely identify non-isolated staging databases as the single largest vulnerability for credential leakage and GDPR non-compliance within internal operations.
FinOps Telemetry and Automated Query Killswitches
The primary hidden cost of internal growth monitoring stems from unconstrained analytics compute. While legacy pre-AI systems relied on post-billing reconciliation, 2026 architectures mandate real-time, deterministic query governance across BigQuery, ClickHouse, and Snowflake.
-- Enforce scan limits directly at the analytical proxy layer
SELECT
    user_id,
    event_name,
    COUNT(*) as total_events
FROM `prod_warehouse.analytics.growth_events`
WHERE _PARTITIONDATE >= DATE_SUB(CURRENT_DATE(), INTERVAL 7 DAY)
GROUP BY 1, 2
LIMIT 5000;
To eliminate runaway query bills, proxy all database transactions through an intermediary middleware layer that performs a dry-run execution estimation. If a user on Retool or Next.js attempts to execute an ad-hoc query with a projected scan volume exceeding 500 MB (or a cost estimate above $0.25), the middleware blocks the execution before hitting warehouse workers.
Furthermore, configure background FinOps monitoring via event-driven webhooks. If any running analytical process exceeds a 30-second execution window or triggers memory thrashing, automated scripts issue immediate KILL QUERY commands and post alert notifications to on-call engineering channels. This guarantees internal growth dashboards never consume more cloud margin than the growth initiatives themselves deliver.
Internal tooling is the operational backbone that dictates growth velocity. Enterprises that rely on fragmented, latency-ridden SaaS dashboards intentionally accept blind spots in their unit economics. By deploying a hybrid Retool and Next.js architecture backed by deterministic data pipelines, you convert telemetry into an asymmetric competitive moat. If your engineering and growth infrastructure lacks this operational rigor, explore my technical audits or review my battle-tested architectural implementations across the build logs to engineer a resilient, high-margin data stack.
Memo Strategici Correlati
Tutti i Memo →Testing video vs static vs carousel ad formats in B2B paid social
Most B2B growth leaders treat creative format selection as a subjective design exercise rather than an upstream engineering problem. In 2026, relying on blen...
Automated usage warnings that prompt plan upgrades: The zero-touch expansion engine
Human-driven account expansion is an operational liability. Relying on Customer Success managers to review usage dashboards and manually pitch tier upgrades ...
Vuoi implementare questa architettura nella tua pipeline?
Evita i lunghi cicli di vendita e le infinite call di scoperta. Invia il tuo collo di bottiglia di acquisizione o conversione per una diagnosi tecnica approfondita in asincrono.