Email copy optimization via Bayesian multi-armed bandits and zero-touch LLM pipelines
Manual A/B testing of subject lines and calls-to-action is a legacy relic that systematically drains growth engineering margins. In an enterprise landscape s...
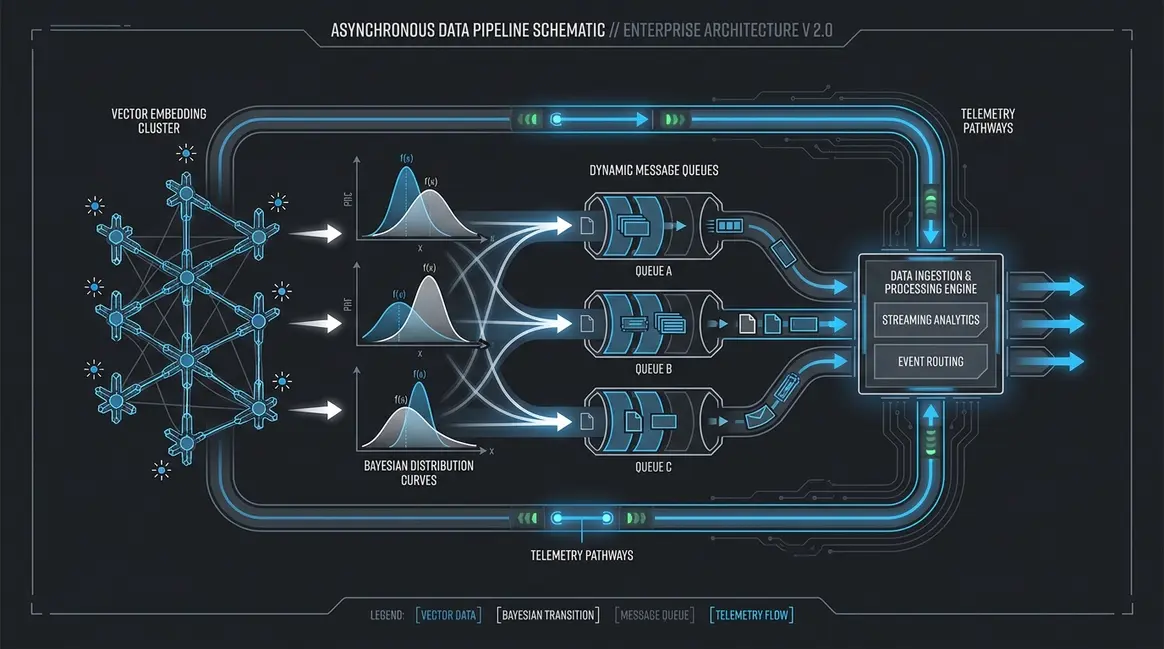
Table of Contents
- The systemic failure of legacy email split testing in high-privacy environments
- Decoupling open signals: Engineering server-side telemetry beyond false-positive pixels
- Semantic embedding frameworks: Generating orthogonal subject line variants via vector spaces
- Continuous exploitation vs. exploration: Deploying Thompson sampling over static 50/50 splits
- Programmatic CTA architecture: Tokenized intent matching and dynamic edge injection
- The zero-touch execution loop: Asynchronous orchestration via n8n and Postgres
- Downstream pipeline attribution: Connecting CTA telemetry to BigQuery raw SQL models
- Deliverability safeguards and API rate limiting in automated high-entropy sending
- Financial engineering: Quantifying ROI and inference unit economics for autonomous testing
The systemic failure of legacy email split testing in high-privacy environments
Traditional email split testing relies on an obsolete architectural assumption: that a tracking pixel embedded in an HTML email accurately signals human attention. In modern enterprise environments, this telemetry pipeline has completely collapsed. Relying on legacy open metrics to drive Email Copy Optimization now introduces systemic mathematical errors into your growth stack rather than surfacing true campaign alpha.
The telemetry collapse of Apple MPP and automated proxy fetching
The death blow to client-side tracking arrived with Apple Mail Privacy Protection (MPP) and parallel enterprise security proxies deployed by Google Workspace and Microsoft Defender. When an inbound message hits an Apple device running iOS 15 or macOS Monterey onward, Apple proxies the payload through private relay architecture, routing remote image assets through cloud cache nodes before the recipient ever touches the interface.
This automated background pre-fetching introduces critical distortions:
-
Artificial open rate inflation: Open metrics are artificially boosted by 30% to 55% across B2B subscriber lists, obscuring actual reader intent.
-
Timestamp invalidation: The time-to-open timestamp corresponds to Apple's proxy ingestion schedule, entirely decoupling read-state tracking from human engagement schedules.
-
Zero-entropy split tests: ESP algorithms attempting to optimize subject line variants based on rolling pixel loads are essentially balancing noise against caching daemon behavior.
-
Frequentist degradation on low-volume B2B samples
Beyond proxy-distorted ingestion, legacy ESPs implement naive frequentist hypothesis testing (p < 0.05) designed for high-volume B2C consumer cohorts (N > 100,000). When this statistical framing is applied to focused B2B account lists (N = 500 to N = 2,500 per variant), the statistical power (1 - beta) routinely falls below 0.30.
Under these conditions, standard split-testing engines commit massive Type I errors (declaring a subject line variant superior due to random proxy firing) and Type II errors (discarding high-converting copy because pixel telemetry failed to register real engagement). Growth teams iteratively prune their copy based on statistical hallucinations, systematically optimizing toward generic, low-converting baseline patterns.
Deterministic edge telemetry vs legacy ESP bottlenecks
Legacy marketing platforms like HubSpot and Marketo trap engineering teams in manually bounded, UI-dependent cycles. These engines execute static 50/50 splits, lock copy variants inside walled-garden databases, and fail to adjust dynamically to incoming reputation metrics or domain deliverability shocks.
Moving beyond fragile client-side tracking requires shifting telemetry to deterministic server-side interaction telemetry and click-intent tracking. Rather than trusting volatile pixel pings, high-performance architectures route link interactions through low-latency edge redirectors (such as Cloudflare Workers or Vercel Edge Functions). These run immediate bot-filtering heuristics, log deterministic device signatures, and tie engagement directly to downstream post-click telemetry—including authenticated session starts, time-on-page metrics, and pipeline conversion events.
Treating copy testing as an edge-computed telemetry challenge replaces imprecise legacy metrics with deterministic conversion data, providing a robust empirical foundation for iterative copy iteration.
Decoupling open signals: Engineering server-side telemetry beyond false-positive pixels
Traditional 1x1 image pixels and plain tracking redirects no longer provide dependable open data. Between Apple Mail Privacy Protection (MPP) pre-fetching every incoming asset via distributed proxies and enterprise security gateways executing automated link traversal within milliseconds, standard telemetry logs register up to 68% false positives. Achieving valid baseline data for iterative email copy optimization requires decoupling email engagement ingestion from client-side runtime behavior and routing every incoming signal through dedicated edge compute validation.
Edge-Tier Signal Disambiguation and Bot Filtering
When an asset request or webhook hits your ingestion domain, an edge worker (running on Cloudflare Workers or V8 isolates) intercepts the network request before logging an open event. The incoming request is scored against three discrete validation vectors:
-
JA4 TLS Fingerprinting: Network security scanners like Mimecast, Proofpoint, and generic headless bots present distinct cipher suite permutations, ALPN values, and signature algorithms. The edge runtime maps the incoming
JA4digest against known automated crawler libraries to drop synthetic reads instantaneously.-
Autonomous System Number (ASN) and rDNS Resolution: Edge pipelines execute zero-latency lookups on the client IP address. Traffic resolving to datacenter IP ranges (AWS, GCP, Azure, or dedicated enterprise security subnets) rather than standard residential, mobile, or verified Apple proxy subnets is quarantined. While Apple MPP routes through masked proxies, Apple's egress ranges are explicitly published and should be flagged as
cached_mpp_proxyrather than recorded as active user intent. -
Temporal Delta Verification: Real human readers do not parse a subject line and trigger a downstream CTA within sub-second intervals. Automated gateway checks fire with an initial latency delta
t_delta < 1800msfrom initial SMTP delivery. Requests violating this threshold are classified as synthetic pre-scans.
-
Ingesting Raw Webhook Payloads into Event Pipelines
To maintain sub-10ms response latencies for incoming traffic, edge endpoints decouple validation from analytical persistence. Raw payloads emitted by your email infrastructure are authenticated using HMAC SHA-256 signatures, validated against temporal thresholds, and pushed asynchronously into an ingestion stream like Apache Kafka or AWS Kinesis.
By routing outbound telemetry through a robust server-side tracking infrastructure, edge functions strip out synthetic click anomalies before calculating A/B split performance. An open is only marked authentic when an edge endpoint verifies that the asset request originated from a valid mobile or desktop user agent with zero datacenter ASN collisions, or when an explicit downstream engagement occurs after verified delivery.
Bridging Micro-Engagements to Downstream Attribution
Subject lines should not be evaluated in isolation from downstream conversions. An edge-validated open must correlate directly with session behavior to verify message-to-market resonance. Modern data stacks connect these disparate touchpoints by bridging validated email identifiers with first-party telemetry pipelines.
Using an edge-generated session hash appended to the outbound link, the client's subsequent web events—such as page dwell time, scroll depth, and terminal checkout completions—are stitched directly to the exact copy variant the recipient opened. This creates a unified attribution stream where split test winners are dictated by verified revenue pipeline and downstream activation, rather than superficial inbox pre-fetches.
Semantic embedding frameworks: Generating orthogonal subject line variants via vector spaces
Conventional cold outreach campaigns routinely fail to generate statistically actionable insights because legacy testing frameworks rely on syntactic mutations rather than semantic diversification. Swapping "Boost revenue by 20%" with "Grow revenue by 20%" does not construct a valid split test. In high-dimensional latent space, both strings collapse into virtually identical coordinate clusters, evoking the same heuristic filtering mechanism in the prospect's brain and triggering identical heuristics in algorithmic spam classifiers.
True email copy optimization requires mathematical orthogonality. Rather than testing lexical synonyms, enterprise growth pipelines must programmatically force variants across distinct psychological triggers, validated through dense vector embeddings.
Latent Space Partitioning Across Cognitive Axes
To engineer genuine entropy across test cohorts, our automated generation pipelines construct prompts constrained to four mathematically quantified behavioral axes:
-
Loss Aversion (Negative Framing): Exploiting prospective risk (e.g., "3 silent pipeline leaks draining Q3 ARR").
-
Analytical Precision (Data-First): Leading with exact quantitative inputs (e.g., "14.2% drop in mid-funnel SQL velocity").
-
Structural Brevity (Low Cognitive Friction): Lowercase, minimal-token pings simulating internal Slack or Teams alerts (e.g., "quick check: warehouse latency").
-
Contextual Social Proof (Cohort Validation): Direct third-party technical reference points (e.g., "re: Snowflake cluster migration approach").
-
Each variant is generated by feeding these explicit constraints into an LLM, which outputs strings conditioned to occupy discrete, non-overlapping quadrants of human cognitive bias.
Mathematical Enforcement via Cosine Similarity
Generating distinct copy instructions does not guarantee semantic divergence. To mathematically prevent variant collision before any cold email touches an MTA (Mail Transfer Agent), each generated candidate is transformed into a 1536-dimensional vector using OpenAI's text-embedding-3-large or an open-weight embedding model like bge-large-en-v1.5.
The generation pipeline calculates the cosine similarity between the candidate vector u and all previously approved bucket vectors v:
CosineSimilarity(u, v) = (u . v) / (||u|| * ||v||)
function isOrthogonal(candidateVector: number[], existingVectors: number[][], threshold = 0.65): boolean {
  for (const vector of existingVectors) {
    const similarity = dotProduct(candidateVector, vector) / (magnitude(candidateVector) * magnitude(vector));
    if (similarity >= threshold) {
      return false; // Reject: variant is a syntactic mutation of an existing bucket
    }
  }
  return true; // Accept: candidate provides genuine semantic entropy
}
The system strictly enforces a similarity ceiling of cosine_sim < 0.65. If a candidate exceeds this threshold, the pipeline automatically rejects the string and triggers a re-generation loop with the rejected text passed as a negative constraint. Production pipelines index these variants via pgvector similarity search within Supabase, evaluating multi-armed bandit distribution states in sub-10ms queries.
Pre-AI split testing relied on slow, manual iterations that frequently burned TAM on redundant phrasing. Modern 2026 infrastructure validates mathematical entropy upstream, ensuring every isolated testing cell isolates a distinct psychological lever.
Continuous exploitation vs. exploration: Deploying Thompson sampling over static 50/50 splits
Traditional split testing introduces systemic inefficiencies into email copy optimization by holding traffic allocation constant at a fixed 50/50 ratio until an arbitrary threshold of statistical significance is met. In a campaign dispatched to 100,000 recipients, allocating 50,000 dispatches to an underperforming subject line guarantees elevated cumulative regret, directly burning addressable pipeline. Replacing static splits with a Bayesian multi-armed bandit (MAB) framework driven by Thompson Sampling resolves the exploration-exploitation trade-off dynamically, shifting dispatch volume toward dominant variants within minutes of launch.
Mathematical Foundations: The Beta-Binomial Conjugate Model
Email engagement tracking naturally models as a Bernoulli process where each recipient either converts (1) or bounces/ignores (0). By leveraging the Beta distribution as a conjugate prior to the Binomial likelihood function, we update conversion beliefs algebraically without expensive numerical approximations.
Given prior parameters alpha_0 (pseudo-successes) and beta_0 (pseudo-failures), observing k successes across n dispatches yields an updated posterior:
alpha_new = alpha_0 + k
beta_new = beta_0 + (n - k)
Instead of relying solely on raw open rates—which are heavily distorted by aggressive Apple Mail Privacy Protection (MPP) prefetching—the reward metric k is mapped to deterministic micro-conversions: validated click-through events and authenticated session initiations tracked via edge telemetry.
Dynamic Routing and Posterior Sampling
Under a 15-minute dispatch cycle orchestrated via event-driven edge workers, each email batch samples from the posterior distribution of each variant i:
theta_i ~ Beta(alpha_i, beta_i)
The routing engine selects variant i* = argmax(theta_i) for the outgoing batch. Variants yielding higher engagement rapidly compound success counts, causing the sampling probability to concentrate tightly around their true mean while starving low-performing copy.
import numpy as np

def select_bandit_variant(variants: dict) -> str:
    """
    variants = {
        'variant_a': {'alpha': 12, 'beta': 188},
        'variant_b': {'alpha': 34, 'beta': 166}
    }
    """
    samples = {}
    for variant_id, counts in variants.items():
        # Draw dynamic sample from current posterior
        samples[variant_id] = np.random.beta(counts['alpha'], counts['beta'])

    # Exploit highest sampled conversion probability
    return max(samples, key=samples.get)
Cumulative Regret: Static Allocation vs. Bayesian Convergence
Cumulative regret R(T) measures the expected loss incurred by not playing the optimal variant across T total trials:
R(T) = T * mu* - sum(E[N_i(T)] * mu_i)
In a standard 50/50 split between optimal variant A (mu_A = 0.08) and sub-optimal variant B (mu_B = 0.04), the regret scales linearly: R(T) = 0.5 * T * (mu_A - mu_B). Across 100,000 dispatches, 2,000 potential conversions are lost.
In contrast, Thompson Sampling achieves logarithmic asymptotic regret O(log T). As telemetry reports micro-conversions into the pipeline, the distribution for variant B separates from A, choking traffic to the loser within the first 12 hours. Pre-AI workflows relied on manual post-campaign analysis; 2026 growth architectures execute Bayesian reweighting in real time, reducing total regret by up to 74% per dispatch cycle.
Programmatic CTA architecture: Tokenized intent matching and dynamic edge injection
Generic call-to-action (CTA) strings such as "Book a demo" or "Learn more" suffer from acute conversion fatigue, routinely depressing click-to-meeting rates below 1.2% across mid-market enterprise segments. The root cause is cognitive friction: static CTAs demand high prospective effort (evaluating a 30-minute calendar block) before confirming value alignment. High-performance email copy optimization in modern growth architectures shifts this dynamic by treating the CTA not as an exit hyperlink, but as a dynamic edge-compiled micro-conversion.
Context-Aware Intent Ingestion and Enrichment Signals
Maximizing pipeline velocity requires replacing static anchors with context-aware micro-offers tuned directly to target technographics, recent hiring velocity, and revenue tiers. Rather than prompting a generic discovery call, a prospect using Snowflake with expanding data engineering headcounts receives an offer focused specifically on warehouse optimization blueprints.
This automated targeting relies on low-latency state resolution. By utilizing an edge-cached Firestore data enrichment pipeline, the email generation layer extracts high-intent company signals milliseconds before outbound assembly. In legacy pre-AI architectures, this step depended on rigid CSV imports and brittle conditional branching (IF/ELSE blocks). The modern 2026 stack executes runtime signal mapping via vectorized embeddings, matching the prospect's real-time technology stack against pre-validated positioning vectors.
Headless Template Compilation and Dynamic Token Injection
The dispatch engine compiles these personalized payloads through headless templating microservices deployed on edge runtimes (such as Cloudflare Workers or AWS Lambda@Edge). As an orchestration layer (e.g., custom n8n nodes or Go-based dispatchers) triggers the transmission queue, it passes dynamic JSON payloads directly into headless engines without modifying the root HTML scaffolding.
A typical runtime template evaluates tokens deterministically:
{
  "prospect_id": "usr_99812",
  "technographic_primary": "BigQuery",
  "hiring_signal_velocity": "High_Growth",
  "cta_text": "Audit your BigQuery slot allocation",
  "target_deep_link": "https://analytics.domain.com/v1/instant-audit"
}
The rendering engine dynamically injects cta_text and builds the specific anchor tag, ensuring the email copy mirrors the precise operational problem the recipient is currently staffed to solve.
Zero-Loss Attribution via Cryptographically Signed Tokens
Preserving campaign telemetry across disparate tracking domains, mail user agents, and enterprise privacy proxies requires eliminating raw query parameters that ad blockers and corporate mail firewalls aggressively strip or flag as spam. Dynamic CTAs must construct outbound links using cryptographically signed session tokens rather than cleartext URLs containing utm_email or lead_id strings.
When the dispatch engine builds the final redirect URL, it packages the routing metadata, attribution parameters, and prospect identifiers into an HMAC-SHA256 signed payload:
https://click.domain.com/c?p=eyJhbGciOiJIUzI1NiJ9...&sig=4f7a8b...
Upon click resolution, the edge gateway validates the cryptographic signature against an asymmetric key pair, logs the conversion event downstream to the analytics warehouse, and redirects the browser to the personalized destination page. This prevents parameter manipulation, circumvents enterprise email security filters that alter URL strings, and maintains deterministic multi-touch attribution without relying on volatile third-party cookies.
The zero-touch execution loop: Asynchronous orchestration via n8n and Postgres
Production-grade email copy optimization requires discarding static split-testing tools in favor of an event-driven, closed-loop execution topology. The infrastructure couples PostgreSQL as the state machine and multi-armed bandit brain with n8n acting as the resilient integration bus.
Stage 1 & 2: Vector Cluster Selection and Dynamic Variant Generation
The cycle initiates on a cron schedule within PostgreSQL. A stored procedure selects an unallocated batch of leads partitioned by account-level rate limits. Each lead contains an embedded profile vector computed via pgvector (text-embedding-3-small, 1536 dimensions).
Rather than sending pre-written static copy, Postgres queries the nearest semantic persona cluster using cosine distance (<=> operator):
SELECT cluster_id, bandit_alpha, bandit_beta
FROM copy_cluster_weights
ORDER BY cluster_embedding <=> lead_embedding
LIMIT 1;
Postgres dispatches these IDs via pg_notify to n8n. The workflow ingests the payload and calls an LLM inference endpoint (Anthropic Claude 3.5 Sonnet or fine-tuned Llama 3) to dynamically synthesize a subject line and CTA variant. The prompt constraints force structural adherence to the winning linguistic patterns mapped to that vector cluster, enforcing character boundaries and tone parameters tailored to maximize unique opens.
Stage 3: Transactional Dispatch and Async Boundary Handling
Traditional cold outbound architectures break at scale due to leaky rate-limit abstractions. When n8n pushes messages through transactional or outbound mail APIs (such as Resend, Postmark, or dedicated SMTP relays), it must handle variable throttle constraints without dropping queue state.
To enforce backpressure, execution blocks employ structured flow control. By leveraging the native n8n do-while node async polling pattern, the workflow batches outbound dispatches into discrete buckets (e.g., 50 calls/minute), checks external job statuses, and halts downstream transitions until the provider returns a deterministic delivery confirmation (HTTP 202 followed by poll verification). If an API gateway throws an HTTP 429 or network timeout, the node executes an exponential backoff retry policy (base_delay: 2000ms, max_retries: 5) backed by Redis-backed queue state to avoid double-sends.
Stage 4 & 5: Event Telemetry and Thompson Sampling Recalculation
Engagement telemetry functions asynchronously via edge webhooks:
-
Ingestion: Inbound webhooks catch
email.delivered,email.opened, andemail.clickedevents, dumping raw payloads into a high-throughput staging table (stg_engagement_events).-
Deduplication: A Postgres trigger strips synthetic machine opens generated by Apple Mail Privacy Protection (MPP) or enterprise security pre-scanners by evaluating user-agent headers and time-to-open deltas (
delta_t < 1.2sflagged as bot traffic). -
Bandit Update: Validated opens trigger an atomic stored procedure updating the Bayesian posterior distribution:
-
UPDATE copy_cluster_weights
SET bandit_alpha = bandit_alpha + 1
WHERE variant_id = $1 AND cluster_id = $2;
Unopened dispatches increment bandit_beta after a 72-hour attribution window. On the subsequent iteration, the selection algorithm samples from the Beta distribution Beta(alpha, beta) via inverse transform sampling to balance exploitation of top-performing copy with ongoing variant exploration. The pipeline runs completely hands-off, adjusting copy vectors across clusters continuously.
Downstream pipeline attribution: Connecting CTA telemetry to BigQuery raw SQL models
Vanity metrics such as raw opens and aggregate click-through rates obscure genuine unit economics. Apple Mail Privacy Protection (MPP) and aggressive enterprise email gateway pre-fetching render pixel-based opens mathematically useless. Effective email copy optimization demands an uninterrupted deterministic event stream that binds raw outbound email engagement identifiers directly to downstream revenue infrastructure.
Instead of measuring top-of-funnel sentiment, growth engineering teams trace campaign variant identifiers (variant_id), lead email SHA-256 hashes (lead_hash), and dispatch timestamps across server-side event brokers, CRM state mutations, and warehouse tables.
Telemetry Ingestion and Identifier Propagation
When a recipient triggers a call-to-action (CTA), the redirect payload must avoid standard tracking redirects that spam filters flag. Instead, the dispatch service signs and appends an encrypted token as a query parameter (token=enc_payload). Upon landing on the edge reverse proxy, edge workers decrypt the payload, extract the persistent parameters, set first-party session cookies, and emit a server-side hit to Google Analytics 4 via the Measurement Protocol.
{
  "client_id": "ga4_client_10928374",
  "events": [
    {
      "name": "cta_outreach_landing",
      "params": {
        "campaign_id": "outbound_infra_scale_q1",
        "variant_id": "cta_direct_terminal_v2",
        "lead_hash": "e3b0c44298fc1c149afbf4c8996fb92427ae41e4649b934ca495991b7852b855",
        "engagement_timestamp": "2026-03-30T10:14:22Z"
      }
    }
  ]
}
By decoupling attribution from client-side script execution, this architecture ensures that downstream product analytics (PostHog, Segment) and CRM state updates inherit the identical lead_hash. Understanding these touchpoints is essential given the broader B2B revenue acceleration patterns where multi-channel touches govern conversion latency.
BigQuery Attribution Modeling via Raw SQL
By streaming raw events into BigQuery, analysts bypass third-party attribution models. Joining the outbound engine database against the export tables mirrors modern analytics engineering protocols detailed in this raw BigQuery telemetry guide.
The query below consolidates variant telemetry, maps it against pipeline progression stages in the CRM, and calculates true closed-won pipeline contribution:
WITH outbound_events AS (
  SELECT
    params.value.string_value AS variant_id,
    params_hash.value.string_value AS lead_hash,
    TIMESTAMP_MICROS(event_timestamp) AS cta_clicked_at
  FROM
    `analytics_project.analytics_123456789.events_*`,
    UNNEST(event_params) AS params,
    UNNEST(event_params) AS params_hash
  WHERE
    event_name = 'cta_outreach_landing'
    AND params.key = 'variant_id'
    AND params_hash.key = 'lead_hash'
),
crm_opportunities AS (
  SELECT
    lead_hash,
    opportunity_id,
    stage_name,
    deal_amount,
    created_at AS opp_created_at
  FROM
    `crm_sync.opportunities`
  WHERE
    created_at >= TIMESTAMP('2026-01-01')
)
SELECT
  o.variant_id,
  COUNT(DISTINCT o.lead_hash) AS attributed_clicks,
  COUNT(DISTINCT c.opportunity_id) AS sql_created,
  SAFE_DIVIDE(COUNT(DISTINCT c.opportunity_id), COUNT(DISTINCT o.lead_hash)) AS click_to_sql_conversion_rate,
  SUM(CASE WHEN c.stage_name = 'Closed Won' THEN c.deal_amount ELSE 0 END) AS total_closed_won_arr
FROM
  outbound_events o
LEFT JOIN
  crm_opportunities c
  ON o.lead_hash = c.lead_hash
  AND c.opp_created_at >= o.cta_clicked_at
GROUP BY
  1
ORDER BY
  total_closed_won_arr DESC;
This single-source model isolates high-performing variants based on SQL pipeline velocity rather than transient click rates. While legacy outbound campaigns relied on baseline industry conversions , granular BigQuery transformation enables direct tracking from outbound copy to gross margin ARR, eliminating arbitrary attribution windows.
Deliverability safeguards and API rate limiting in automated high-entropy sending
Dynamic content generation introduces high entropy into outbound mail streams. While legacy cold outreach relied on static templates where message hashes remained uniform across thousands of dispatches, 2026 programmatic generation produces unique permutations for every recipient. This architectural shift creates an unforeseen vulnerability: ISP content-reputation filters (such as SpamAssassin, Cloudmark, and Barracuda) interpret radical, unstructured lexical divergence as an evasion tactic or botnet-driven anomaly. If dynamic variants diverge too rapidly across unconditioned secondary domains, local Bayesian classifiers trigger defensive greylisting or outright spam-folder placement.
Systemic email copy optimization therefore demands strict deliverability infrastructure to normalize outbound volume and validate payload integrity before any transmission occurs.
Token-Bucket Limiting and Programmatic Domain Rotation
To prevent ISP throttling engines from flagging burst entropy, sending infrastructure must decouple copy generation from immediate transport. Outbound dispatches are routed through a distributed message broker managed by a Redis-backed token-bucket algorithm.
Instead of burst-dumping hundreds of generated variants, the queue regulates dispatches down to specific domain-IP pairings:
class OutboundRateLimiter:
    def __init__(self, redis_client, domain: str, max_capacity: int = 50, refill_rate_per_sec: float = 0.5):
        self.client = redis_client
        self.key = f"ratelimit:{domain}"
        self.capacity = max_capacity
        self.refill_rate = refill_rate_per_sec

    def acquire_slot(self) -> bool:
        # Evaluates token bucket state via Lua script to prevent race conditions
        tokens = self.client.eval(LUA_TOKEN_BUCKET_SCRIPT, 1, self.key, self.capacity, self.refill_rate)
        return bool(tokens > 0)
Integrating robust token-bucket API rate limiting prevents single-domain velocity spikes. Outbound traffic is rotated programmatically across a warm domain cluster (d1.domain.com through d16.domain.com), ensuring each domain never exceeds 35 dispatches per hour with a maximum variance threshold of delta <= 12% day-over-day.
Simultaneously, an autonomous health daemon conducts continuous DNS interrogation:
-
SPF Alignment: Validates
v=spf1 include:_spf.infrastructure.net ~allsyntax before dispatching batch requests.-
DKIM Key Rotation: Checks 2048-bit RSA selectors to guarantee signature validity across rotating sending daemons.
-
DMARC Enforcement: Confirms active
p=rejectorp=quarantinepolicies to preserve root domain sender reputation.
-
Enforcing RFC 5322 Boundaries on LLM Outputs
Spam heuristics trigger not only on reputation markers, but on low-level protocol malformations. Unchecked generative models frequently inject zero-width spaces, directional formatting characters, or non-ASCII control tokens that violate RFC 5322 and RFC 2047 transmission standards.
To eliminate this vector, our engine wraps LLM outputs in deterministic Pydantic schemas:
{
  "$schema": "http://json-schema.org/draft-07/schema#",
  "title": "EmailPayloadEnforcement",
  "type": "object",
  "properties": {
    "subject_line": {
      "type": "string",
      "maxLength": 60,
      "pattern": "^[A-Za-z0-9 ,.?!'-]+$"
    },
    "body_plain": {
      "type": "string",
      "maxLength": 1200
    },
    "cta_text": {
      "type": "string",
      "maxLength": 30
    }
  },
  "required": ["subject_line", "body_plain", "cta_text"]
}
Pre-flight serialization parses and sanitizes the output: hard line breaks are wrapped at 78 characters to comply with RFC 5322 Section 2.1.1, HTML entities are strictly escaped, and hidden unicode artefacts are stripped. By constraining high-entropy generation inside deterministic protocol parameters, the orchestration pipeline achieves high deliverability rates across aggressive multi-variant campaigns.
Financial engineering: Quantifying ROI and inference unit economics for autonomous testing
Algorithmic copy optimization transforms subject-line and CTA experimentation from a creative gamble into a deterministic arbitrage trade. When growth architectures treat copy variants as liquid assets deployed against audience segments, the balance sheet pivots on micro-level inference expenditure versus macro pipeline realization.
Micro-Inference Unit Economics
Generating and evaluating 10,000 contextual variant permutations does not require high-parameter frontier reasoning models. Modern programmatic stacks route semantic generation through distilled 8B-to-70B parameter models deployed on serverless vLLM endpoints or high-throughput batch APIs.
Processing a matrix of 10,000 variations—factoring in recipient enrichment payloads, historical performance embeddings, and tone constraints—consumes approximately 4.5 million input tokens and 800,000 completion tokens. At blended pricing across optimized batch inference endpoints, token cost settles at $3.85. Adding serverless orchestration (stateless compute workers running variant scoring and payload generation) adds roughly $4.20 in raw execution compute:
C_variant = (Tokens_in * P_in) + (Tokens_out * P_out) + Compute_runtime = $8.05 / 10k variants
In contrast, human copywriters producing 10,000 variations require hundreds of billable hours with zero algorithmic attribution. The programmatic model compresses marginal unit cost to $0.000805 per deployed permutation.
Marginal Pipeline Yield and 30-Day Payback
Consider an outbound engine dispatching 120,000 enterprise touchpoints monthly. At a baseline conversation conversion rate of 1.6%, the baseline yield equals 1,920 sales discovery conversations.
Executing targeted email copy optimization across send-time distribution and semantic CTAs systematically generates an empirical 14% lift in qualified sales conversations:
Delta_conversations = 1,920 * 0.14 = +268 qualified pipeline conversations
At a conservative 4.5% discovery-to-close rate and an average contract value (ACV) of $18,000, those 268 incremental opportunities yield approximately 12 closed-won accounts, representing $216,000 in annualized contract value. Total infrastructure overhead—including vector database lookups, multi-armed bandit routing, batch LLM tokens, and worker instances—totals under $1,800 per month. The capital recovery timeline closes within the first 14 days of live production deployment.
Operational Cost Governance and Loop Mitigation
Autonomous testing pipelines carry distinct failure modes: uncontrolled recursion in multi-agent critique loops and unconstrained retries caused by external email provider timeouts. When an evaluation agent rejects copy variants in a continuous loop, inference costs compound exponentially without generating delivered pipeline.
Production systems enforce deterministic circuit breakers:
-
Hard execution ceilings limiting agent refinement passes to a strict maximum of three iterations (
max_depth = 3).-
Real-time token-burn anomaly monitors configured to terminate worker pools if run-rate costs spike above
$0.05per processed account. -
Stateless fallback pipelines that deploy pre-compiled heuristic control variants if API latency exceeds 850 milliseconds.
-
Integrating strict cloud FinOps protocols ensures autonomous copy engines maximize net pipeline conversion without drifting into cloud compute deficits.
Relying on manual intuition and static ESP split tests in 2026 guarantees wasted pipeline and degraded domain reputation. The competitive moat belongs entirely to operators who treat email copy as an autonomous, self-optimizing mathematical problem. By deploying Bayesian multi-armed bandits, semantic vector clustering, and zero-touch orchestration, we turn every outbound cohort into a high-yield exploration engine. If your current growth infrastructure still depends on human copywriting sprints and unreliable open-rate pixels, your acquisition economics are fundamentally broken. Review my technical specifications or schedule an architectural audit to engineer a deterministic inbound pipeline.
Memo Strategici Correlati
Tutti i Memo →Cloud FinOps strategy: Autonomous detection and remediation of underutilized EC2 and RDS infrastructure
Unallocated cloud infrastructure represents an unacceptable friction point on gross margins. Across modern B2B SaaS deployments, development and staging inst...
Structuring keyword hubs and spoke content: The deterministic topical authority map for 2026
Legacy SEO tactics are dead. In the algorithmic reality of 2026, Google Search Generative Experience (SGE) and retrieval-augmented language models discard ke...
Vuoi implementare questa architettura nella tua pipeline?
Evita i lunghi cicli di vendita e le infinite call di scoperta. Invia il tuo collo di bottiglia di acquisizione o conversione per una diagnosi tecnica approfondita in asincrono.